Disclaimer
Is this plugin open source? Yes
Is this plugin completely free? No — the plugin itself is free and open source, but optional cloud LLM providers may charge for API usage. You can also use local models through Ollama.
Is this plugin vibe-coded beyond the author’s ability to comprehend how it works? No
Community Directory: Vault Coach - Obsidian Plugin
Vault Coach — Turn Your Obsidian Vault Into a Learning System
Most AI plugins for note-taking focus on one workflow:
You ask questions, and the AI gives you answers.
I wanted to explore the opposite direction as well:
What if your own notes could ask you questions back?
That idea became Vault Coach, an open-source Obsidian plugin built around RAG, exam generation, semantic knowledge graphs, and mastery tracking.
The goal is not to replace learning with AI, but to use AI to make active recall, testing, review, and knowledge discovery easier inside an existing Obsidian vault.
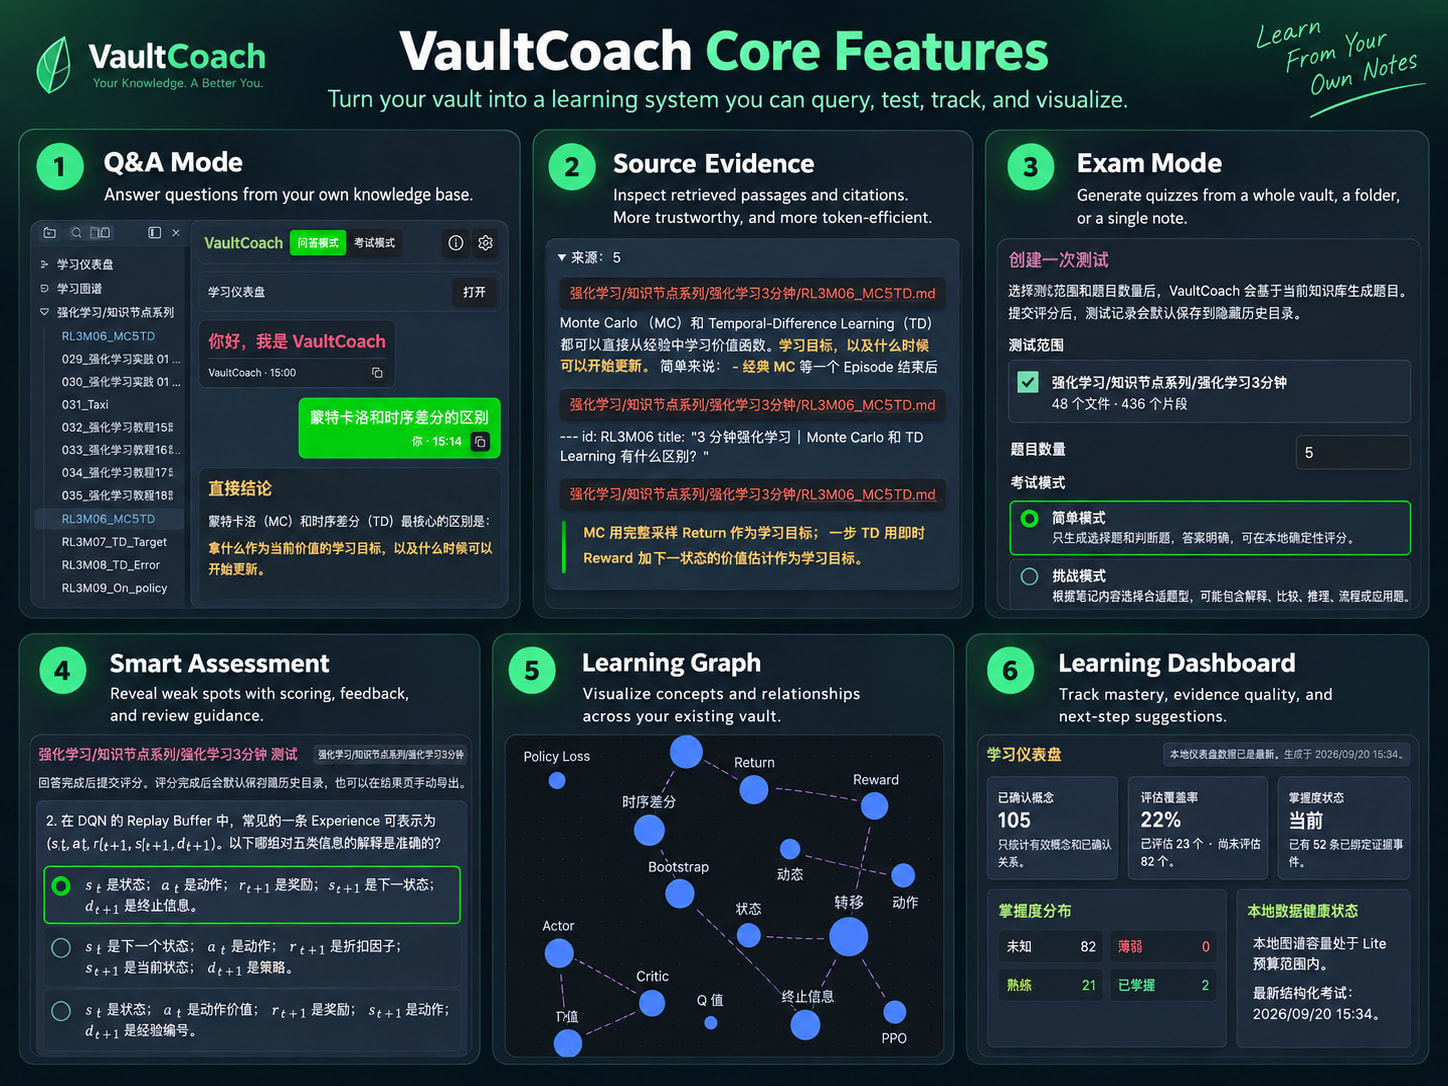
Why I built it
AI makes it extremely easy to get explanations.
For example, when working on a software or machine-learning project with tools such as ChatGPT, Claude, Cursor, or Codex, it is possible to produce a fairly complete implementation very quickly.
The problem appears later when someone asks:
- Why was this architecture chosen?
- How does the retrieval pipeline work?
- Why is reranking needed?
- What alternatives could have been used?
- Can you explain the underlying concept without looking at the generated answer?
Sometimes we discover that we recognize the explanation when we see it, but cannot reproduce it ourselves.
That is the problem Vault Coach is trying to address.
I do not want to make AI slower or less useful. I want to bring some of the learning process back into the workflow:
retrieve → explain → test → identify weak points → review
1. Ask questions from your own vault
Vault Coach can retrieve information from Markdown notes and text-based PDFs using:
- keyword search
- vector retrieval
- hybrid retrieval
The retrieved passages are then used as context for the configured LLM.
For example, in my own vault I maintain a collection of reinforcement-learning notes. I can ask:
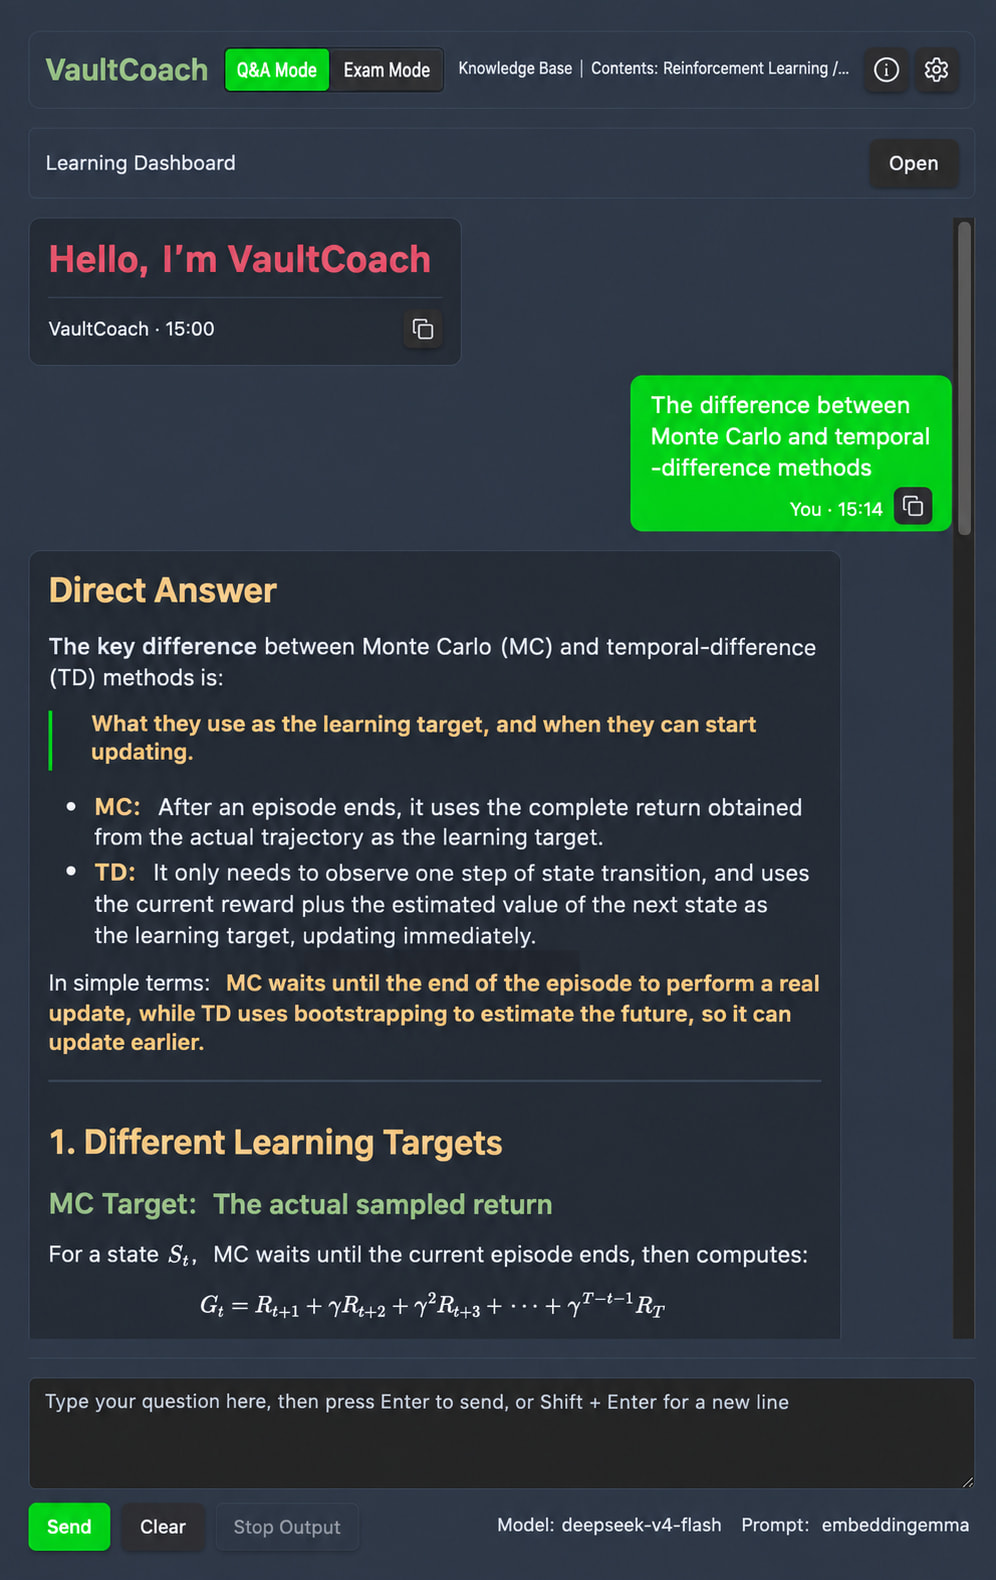
What is the difference between Monte Carlo and Temporal-Difference learning?
Vault Coach first retrieves relevant sections from the vault and then generates an answer based on those sources.
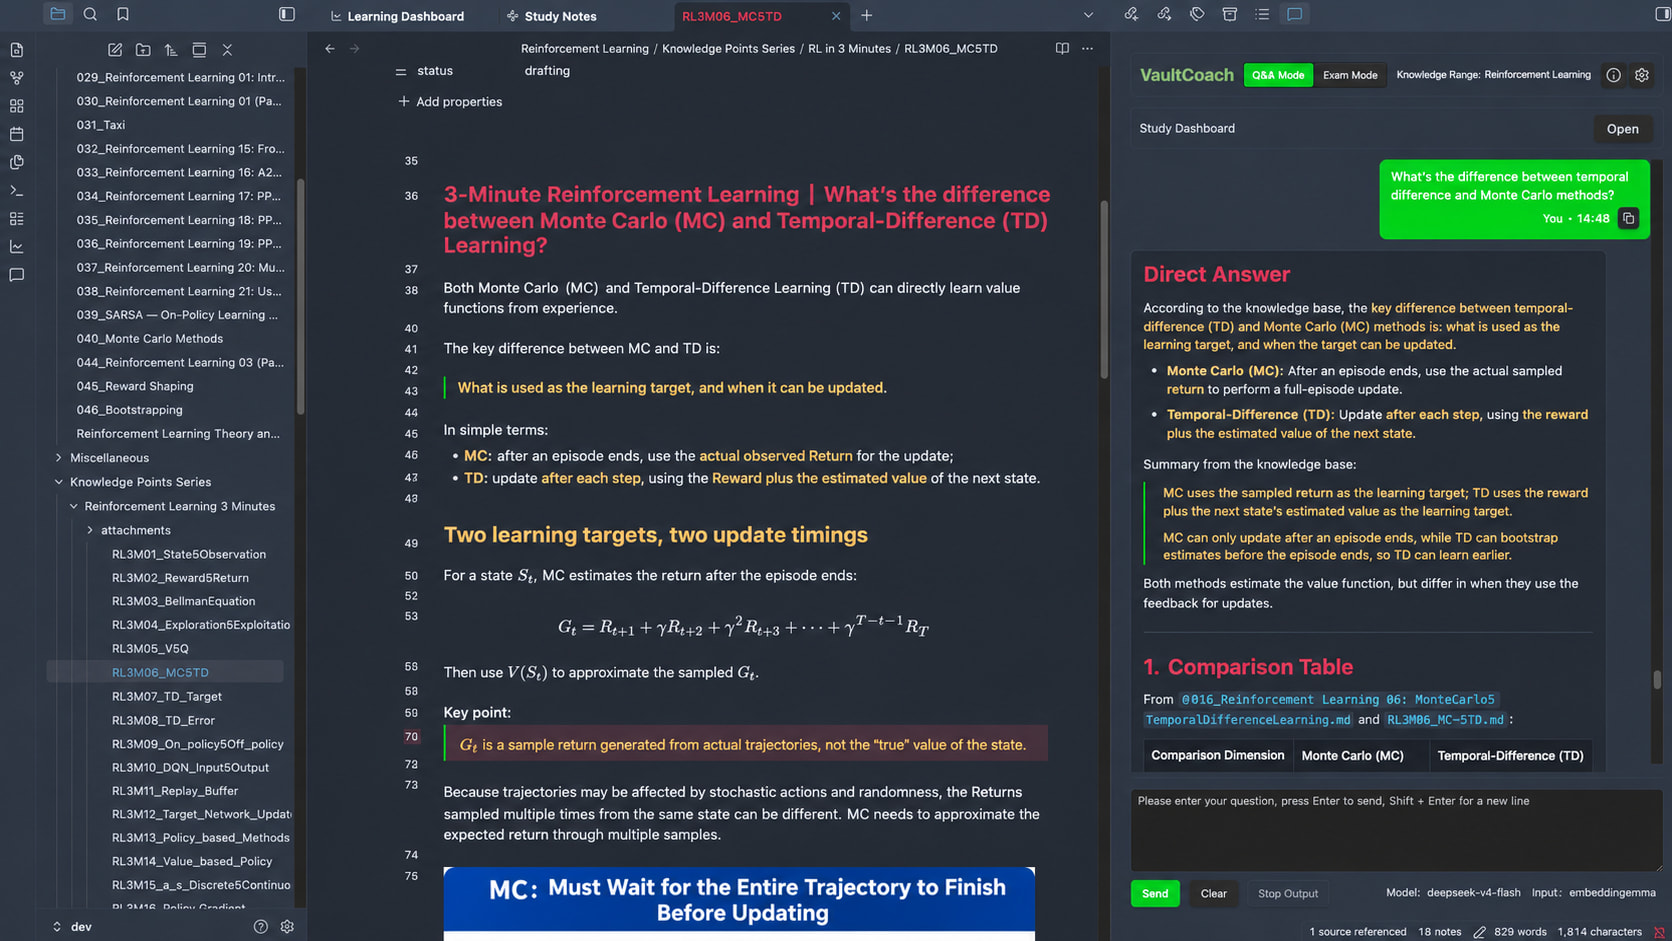
A closer view of the Q&A interface:
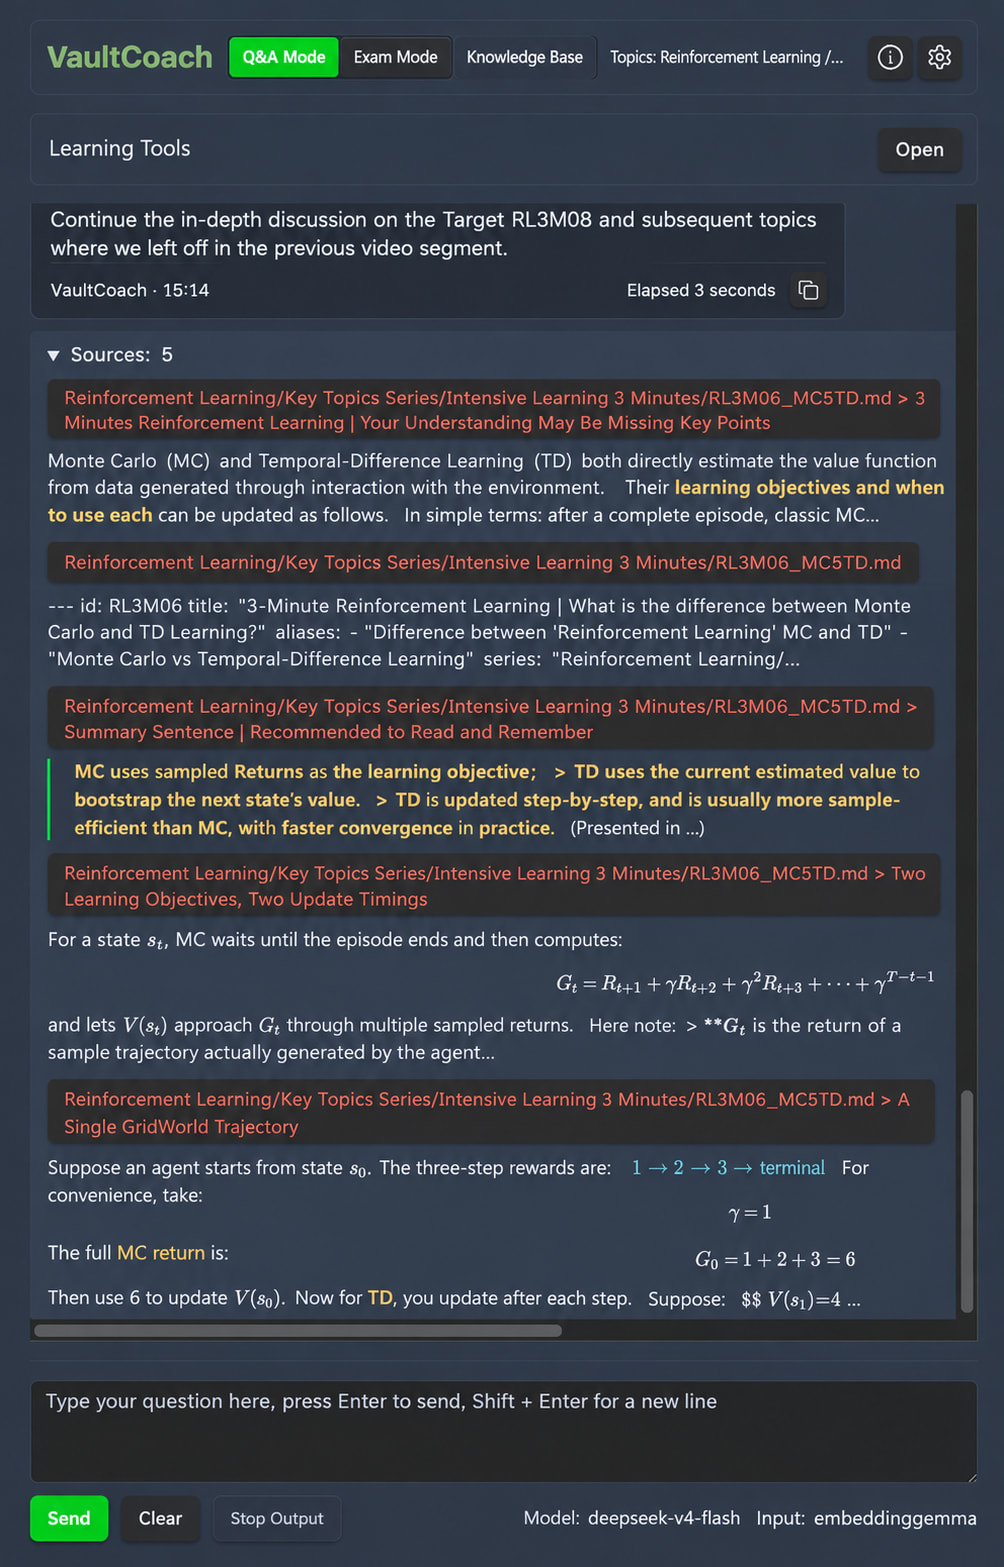
Source evidence
Vault Coach also exposes the passages used to generate an answer.
Instead of only seeing an LLM response, you can inspect the notes, sections, and retrieved evidence behind it.
This is useful both for verification and for navigating back into the original knowledge base.
Retrieval also means the model does not need the entire vault in its context window for every question.
Only relevant passages are sent to the model, which can reduce unnecessary token usage compared with sending large amounts of unrelated vault content.
2. Reverse the workflow: let your vault test you
RAG is useful, but I did not want Vault Coach to stop at question answering.
The second major feature is Exam Mode.
You can create an exam from:
- the entire vault
- a folder
- a specific part of the knowledge base
For example, here I selected only my “Reinforcement Learning in 3 Minutes” notes.
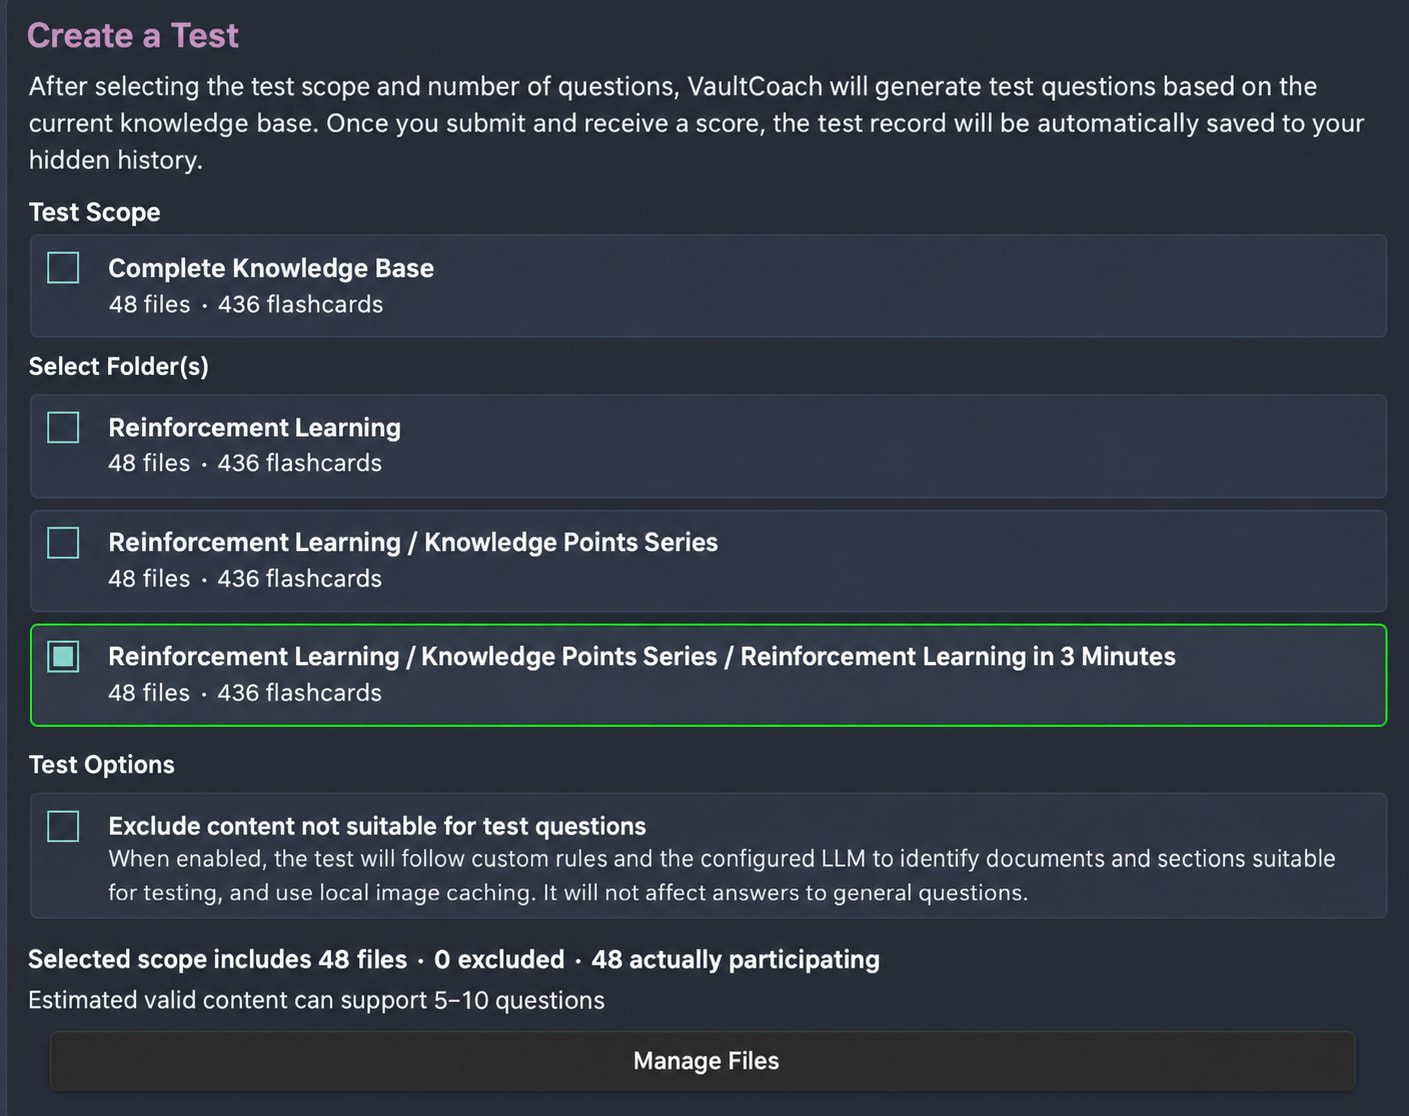
The exam workflow also supports different modes and adaptive study goals.
For example, I can tell Vault Coach to prioritize knowledge that has not yet been mastered.
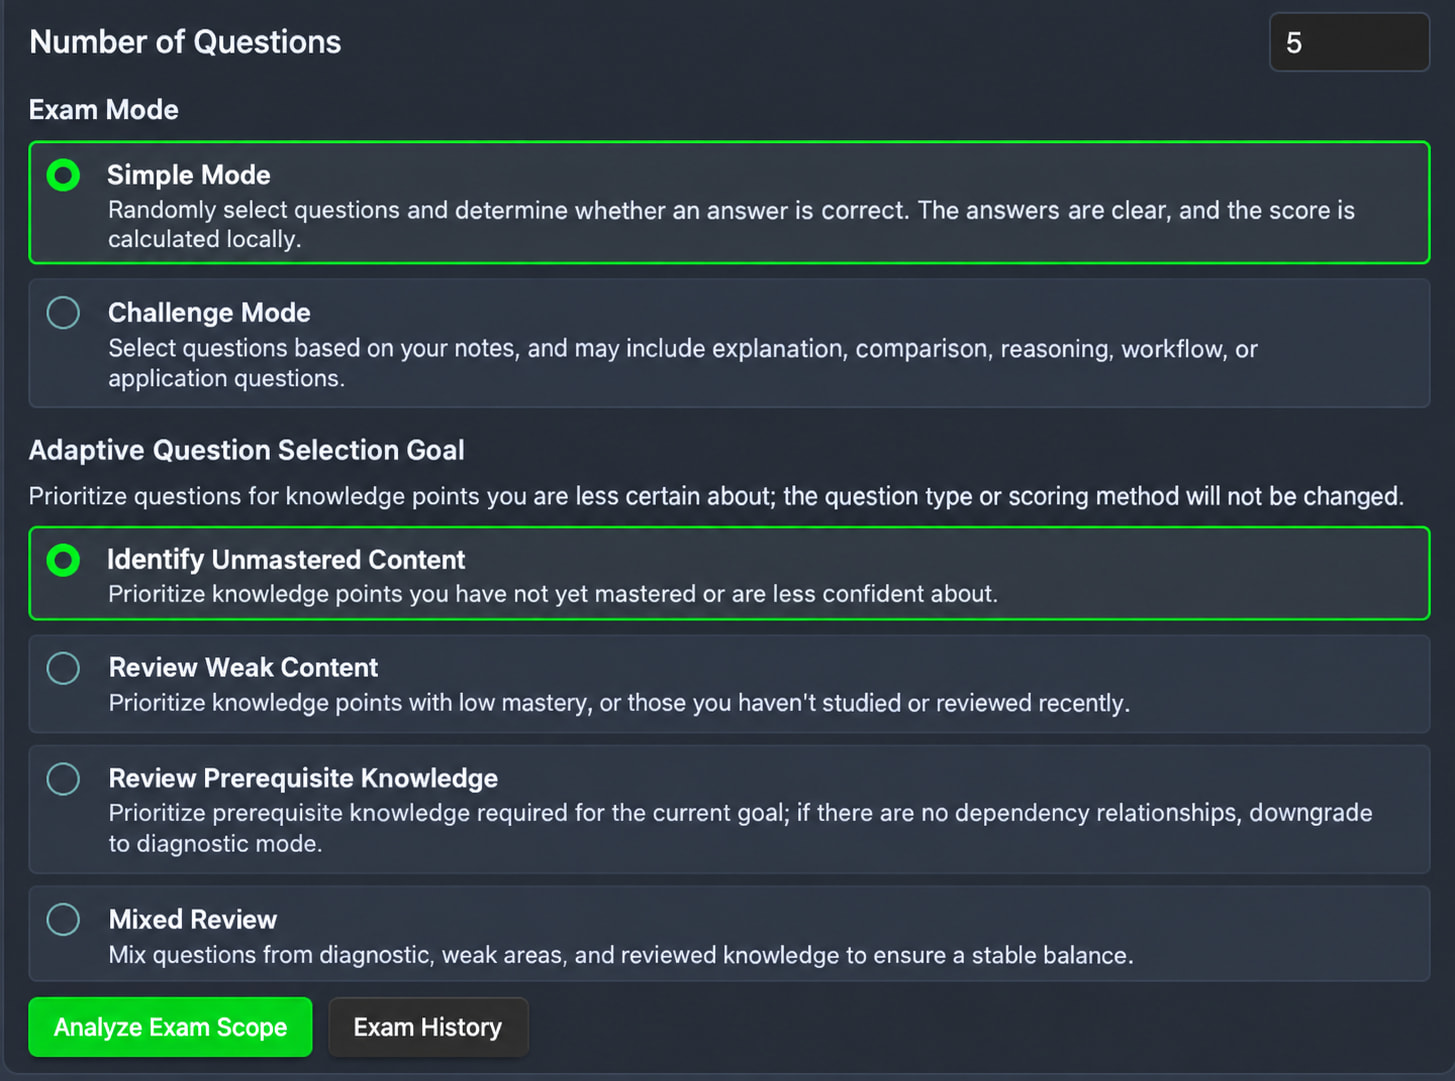
Then Vault Coach generates questions from the selected material.
Instead of the AI answering, the user has to answer.
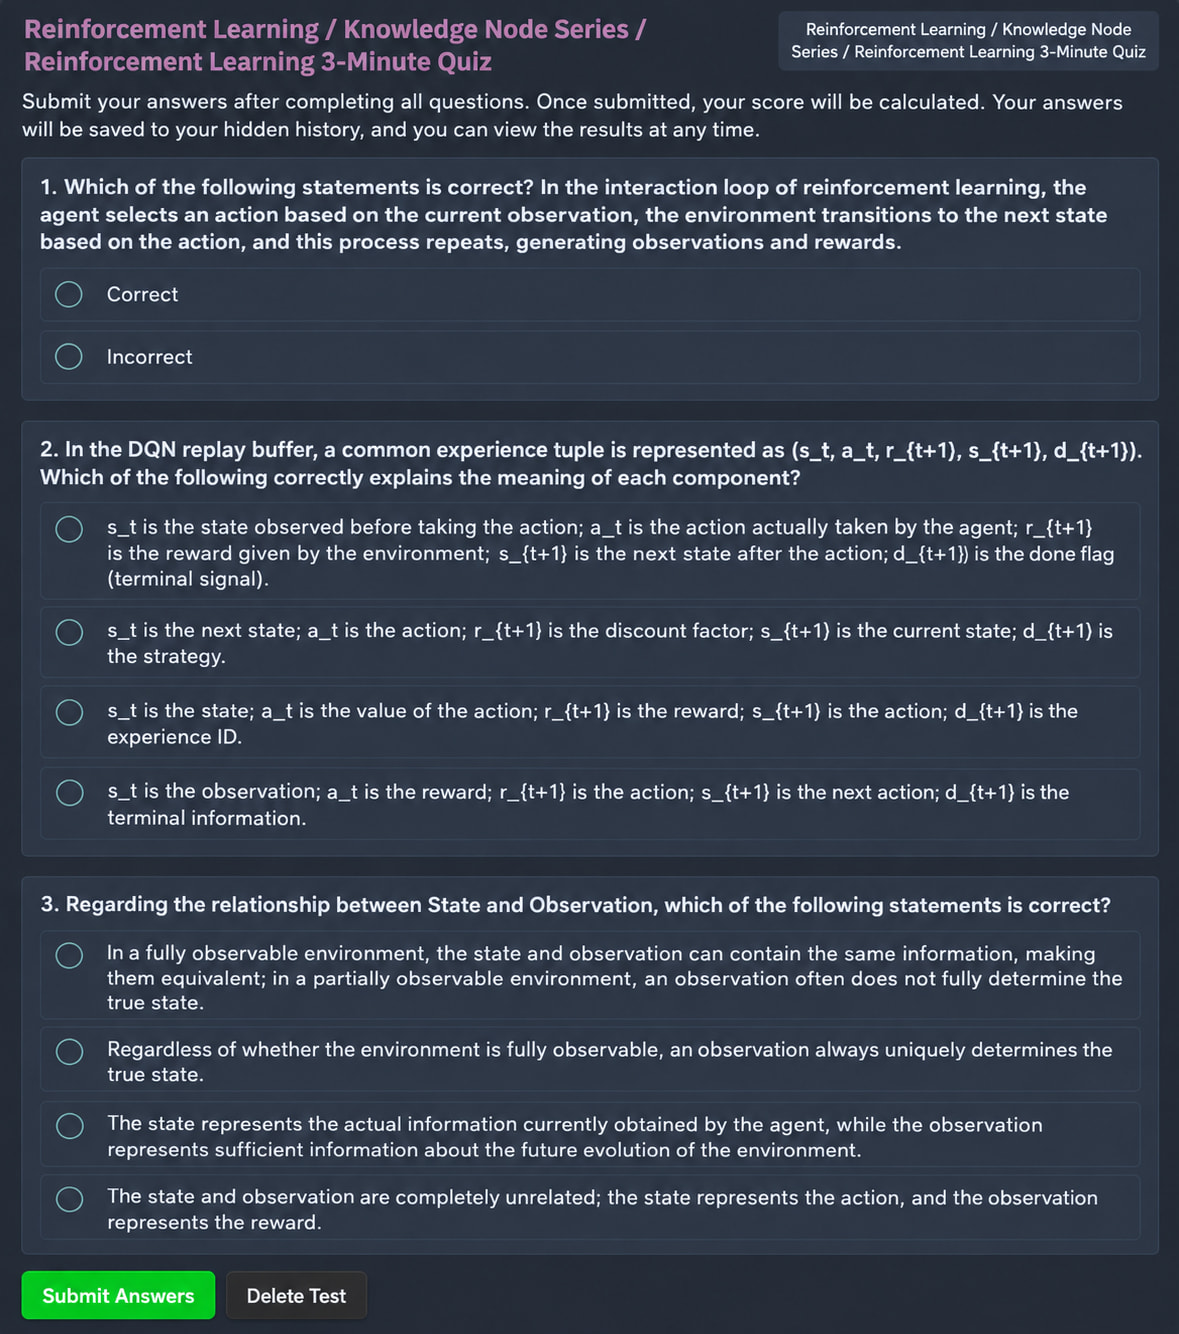
The basic idea is:
Normal RAG
Knowledge Base → AI → Answer
Vault Coach Exam Mode
Knowledge Base → AI generates questions → User answers → Evaluation → Learning evidence
Exam results can be stored locally and used later for mastery tracking and review recommendations.
This is the part of the plugin I consider most important.
If I only recognize the answer after seeing it, I probably do not understand the topic as well as I think I do.
3. Turn an existing vault into a semantic learning graph
Another problem appears once a vault becomes large.
You may have dozens or hundreds of notes, but it becomes difficult to answer:
- What concepts are actually inside my vault?
- How are they related?
- Which concepts are isolated?
- Which topics have I already studied?
- Where are the gaps?
Obsidian backlinks are very useful for showing relationships between notes.
Vault Coach tries to add another layer: relationships between concepts inside those notes.
The Learning Graph extracts concepts from existing content and visualizes their relationships.
In my reinforcement-learning vault, this produces concepts such as:
- DQN
- TD Learning
- Bootstrap
- Reward
- Return
- Actor
- Critic
- Policy Gradient
- Target Network
- Value Function
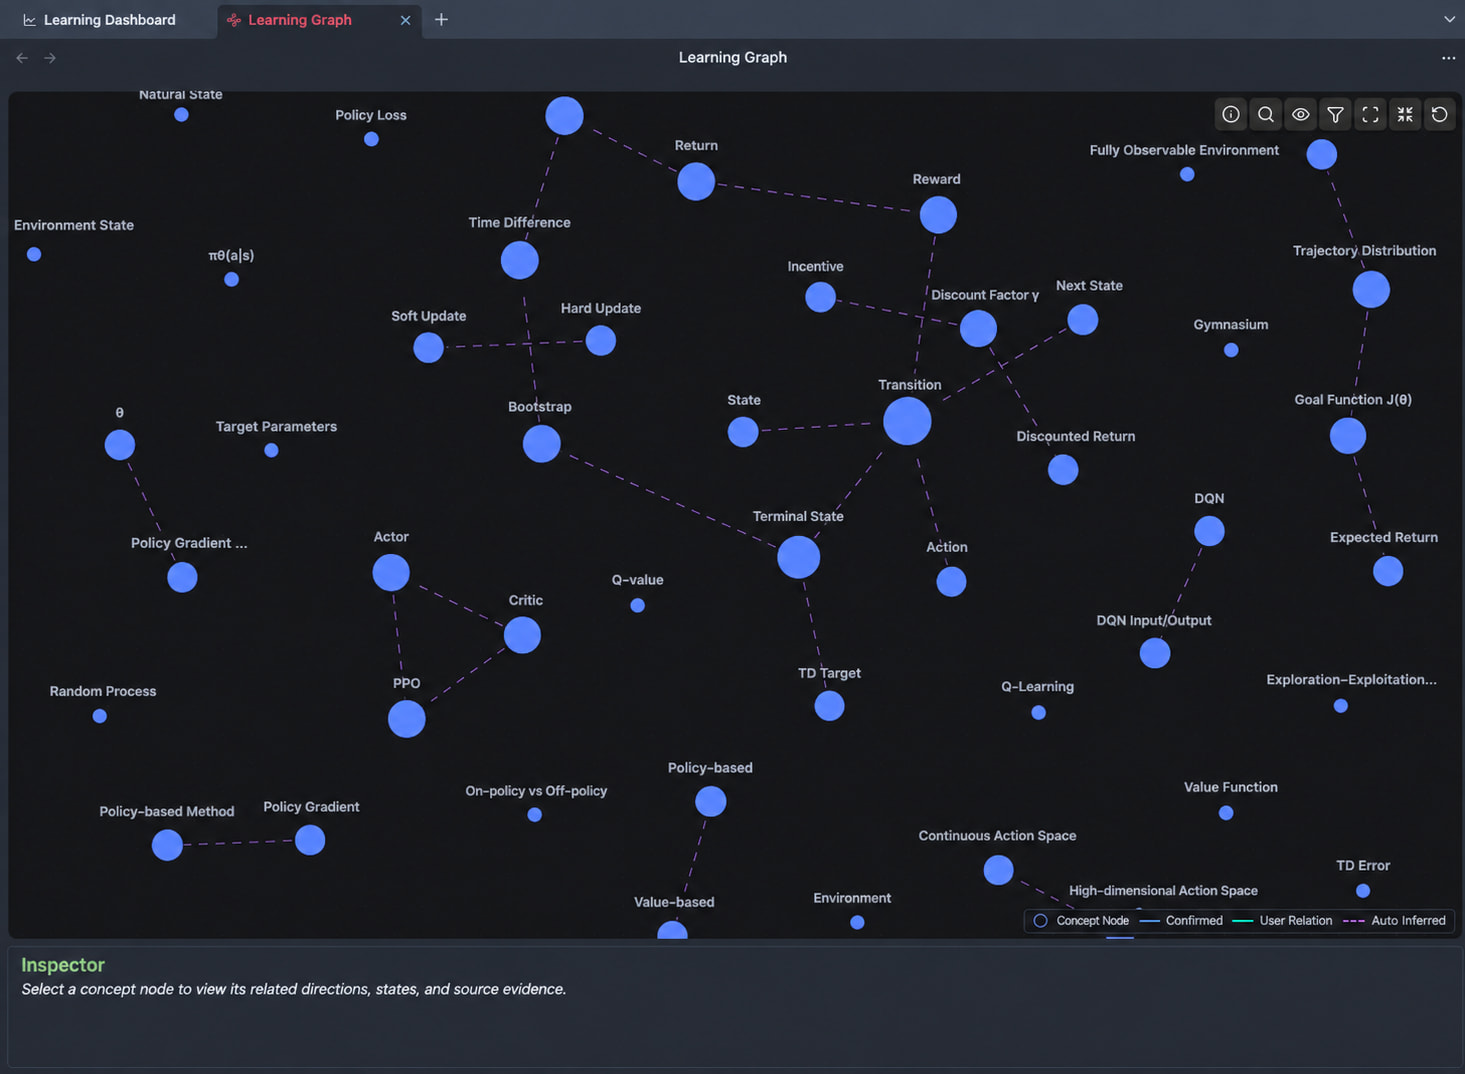
Human review is part of the graph workflow
I do not want every relationship inferred by an LLM to automatically become part of the knowledge graph.
Vault Coach therefore includes a Concept Review workflow.
You can inspect:
- the concept
- aliases
- relationships
- source evidence
and decide whether the extracted knowledge should be confirmed or corrected.
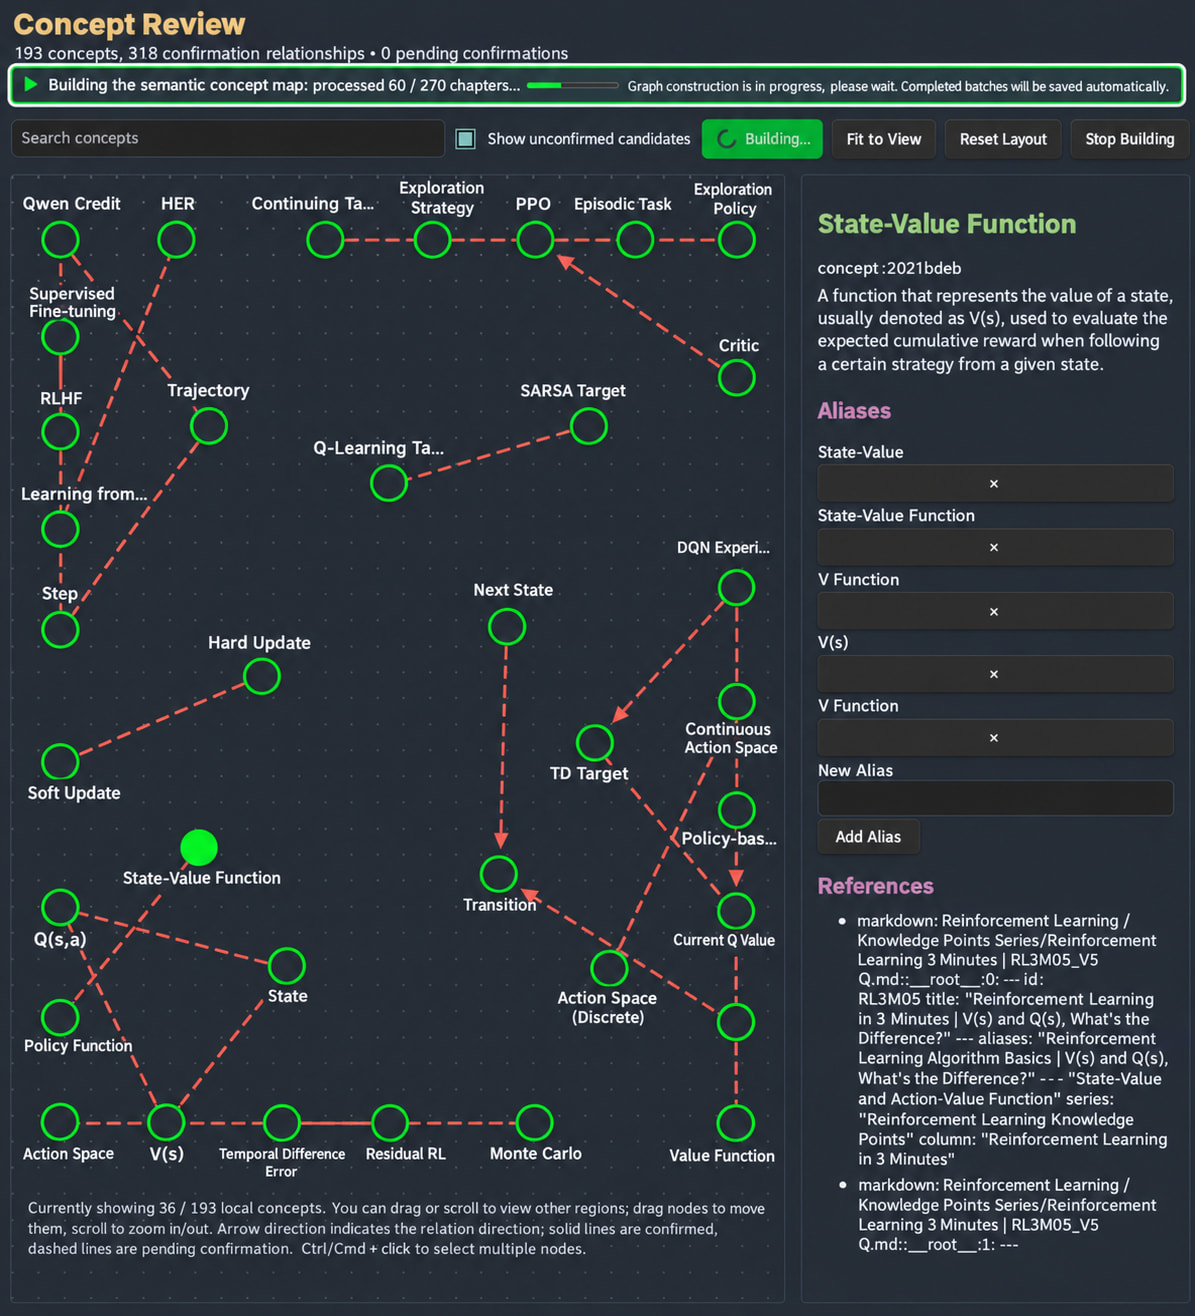
This is intentional: the knowledge graph should remain inspectable rather than becoming an opaque collection of AI-generated relationships.
4. Track what you actually know
Exam results and confirmed concepts can also be aggregated into a Learning Dashboard.
The dashboard currently tracks information such as:
- confirmed concepts
- evaluation coverage
- mastery status
- structured exams
- evidence quality
- mastery distribution
- next study recommendations
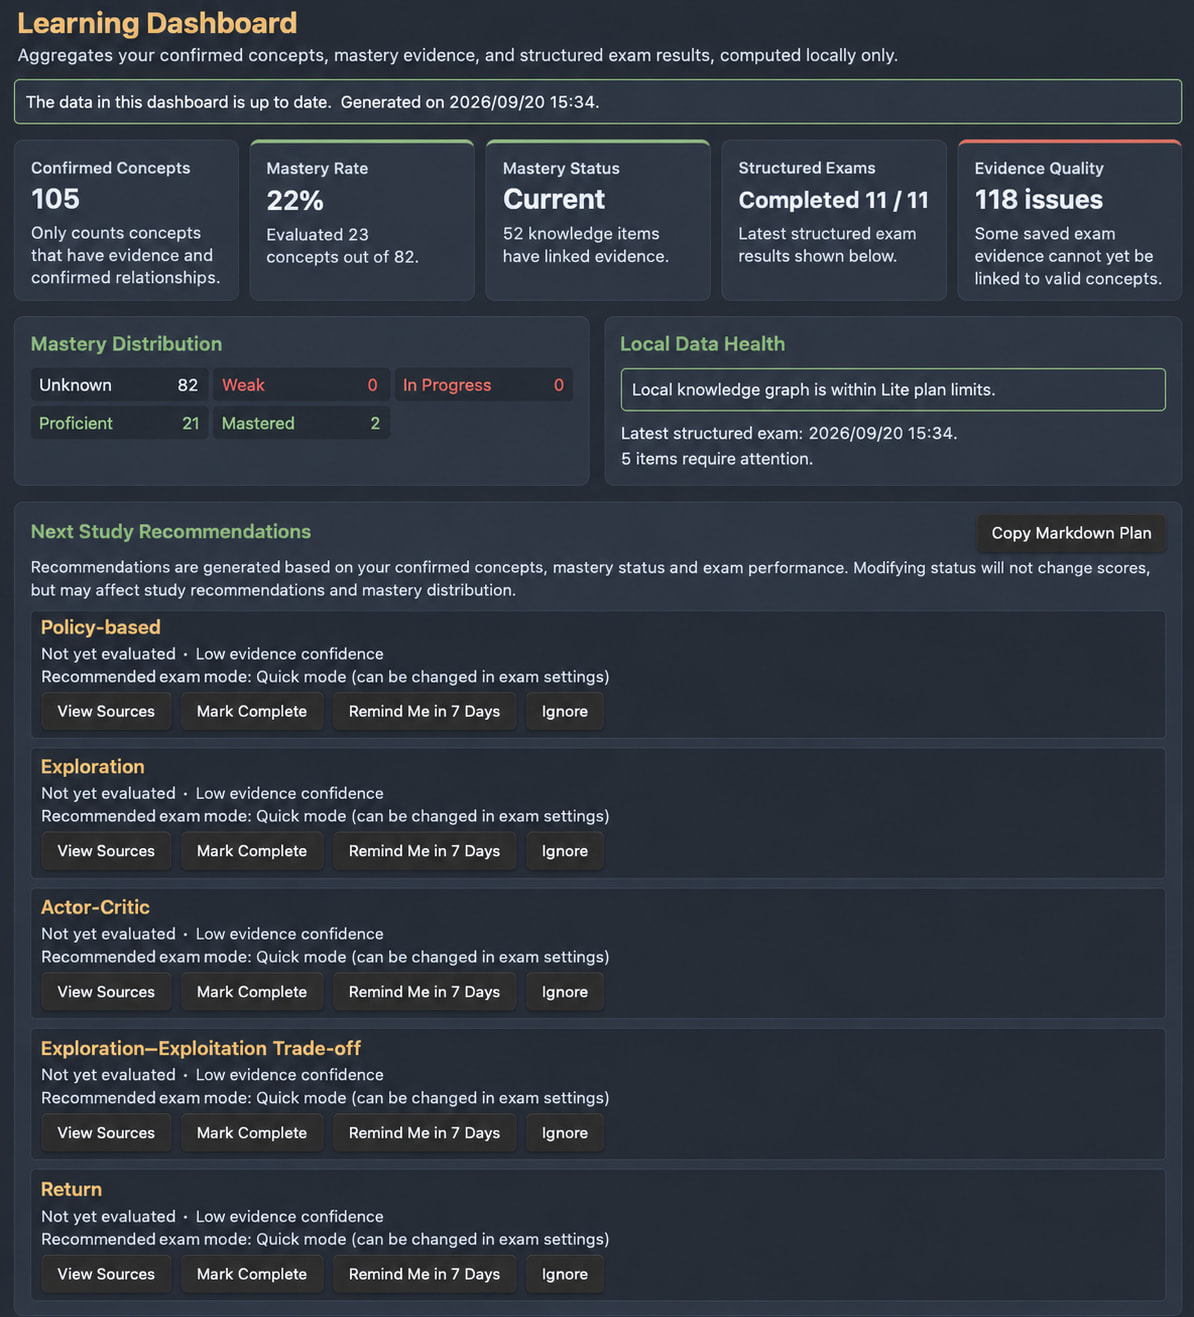
The long-term goal is to make the learning loop explicit:
Capture knowledge
→ Retrieve it
→ Ask questions
→ Take exams
→ Identify weak concepts
→ Review
→ Test again
Instead of accumulating more and more notes that are rarely revisited.
Privacy, local models, and token usage
Vault Coach is designed with local-first workflows in mind.
The knowledge graph, learning records, and related study data are intended to remain closely tied to the local Obsidian vault.
For LLM features, the exact privacy properties depend on the backend you choose.
If you use a remote LLM API, retrieved context may be sent to that provider.
If you use a supported local model through Ollama, LLM processing can remain on your own machine.
RAG also limits the amount of context sent to the model by retrieving relevant passages first instead of passing large portions of the vault into every request.
This can reduce token usage when using token-based cloud APIs.
Current limitations
Vault Coach is still actively evolving.
A few important limitations:
- PDF support currently focuses on text-based content.
- Image-heavy PDFs, diagrams, and embedded visual information are not fully understood.
- Knowledge-graph extraction still benefits from human review.
- Retrieval and answer quality depend on the configured embedding model and LLM.
- Building semantic graphs for large vaults can take time.
- Mastery tracking is still being refined as the exam and evidence model evolves.
I would rather make these limitations explicit than present the plugin as a fully solved learning system.
Installation
Vault Coach is available through the Obsidian Community Plugins directory.
Settings → Community Plugins → Browse → Search for “Vault Coach”
Source code:
https://github.com/Wanjin5508/vault-coach
Feedback
I would especially appreciate feedback from people who use Obsidian for:
- technical learning
- university study
- exam preparation
- software engineering notes
- machine-learning / AI research
- large long-term knowledge bases
I am particularly interested in feedback on:
- exam workflows
- adaptive question selection
- knowledge-graph quality
- large-vault performance
- local LLM workflows
- mastery tracking
Bug reports and feature requests are welcome on GitHub.
Future Vault Coach updates will also be posted in this thread, as required by the forum rules.
Thanks for trying it.